Fairness Beyond Demographics: Optimizing Performance Across Appearance-Based Hidden Cohorts in Medical Imaging
Abstract
Medical image analysis models can exhibit performance disparities across patient subgroups, raising concerns about clinical safety and fairness. Existing approaches typically address this problem by optimizing fairness with respect to predefined demographic attributes (e.g., sex or age), often considered in isolation. However, such strategies may overlook more informative latent structures within the data and do not scale well when multiple demographic attributes are combined due to subgroup sparsity. We introduce the label-free Hidden-Cohort Fairness (LHCF) paradigm, which shifts the focus from demographic-based fairness to appearance-driven fairness. Instead of relying on explicit demographic labels, LHCF discovers latent subpopulations directly from image representations by clustering samples into appearance-based cohorts and optimizing fairness across them. This approach reveals underlying sources of model error and mitigates disparities without suffering from the combinatorial explosion of multi-attribute subgroup definitions. We evaluate LHCF on our proposed benchmark, HIDFairBench, demonstrating state-of-the-art fairness performance across both single and multiple demographic attributes. Importantly, LHCF achieves these improvements without requiring demographic labels during training, making it a practical and scalable solution for real-world clinical settings where metadata may be incomplete or unavailable. Our results highlight hidden-cohort fairness as a robust and effective alternative to conventional demographic-based fairness optimization.
LHCF Framework Overview
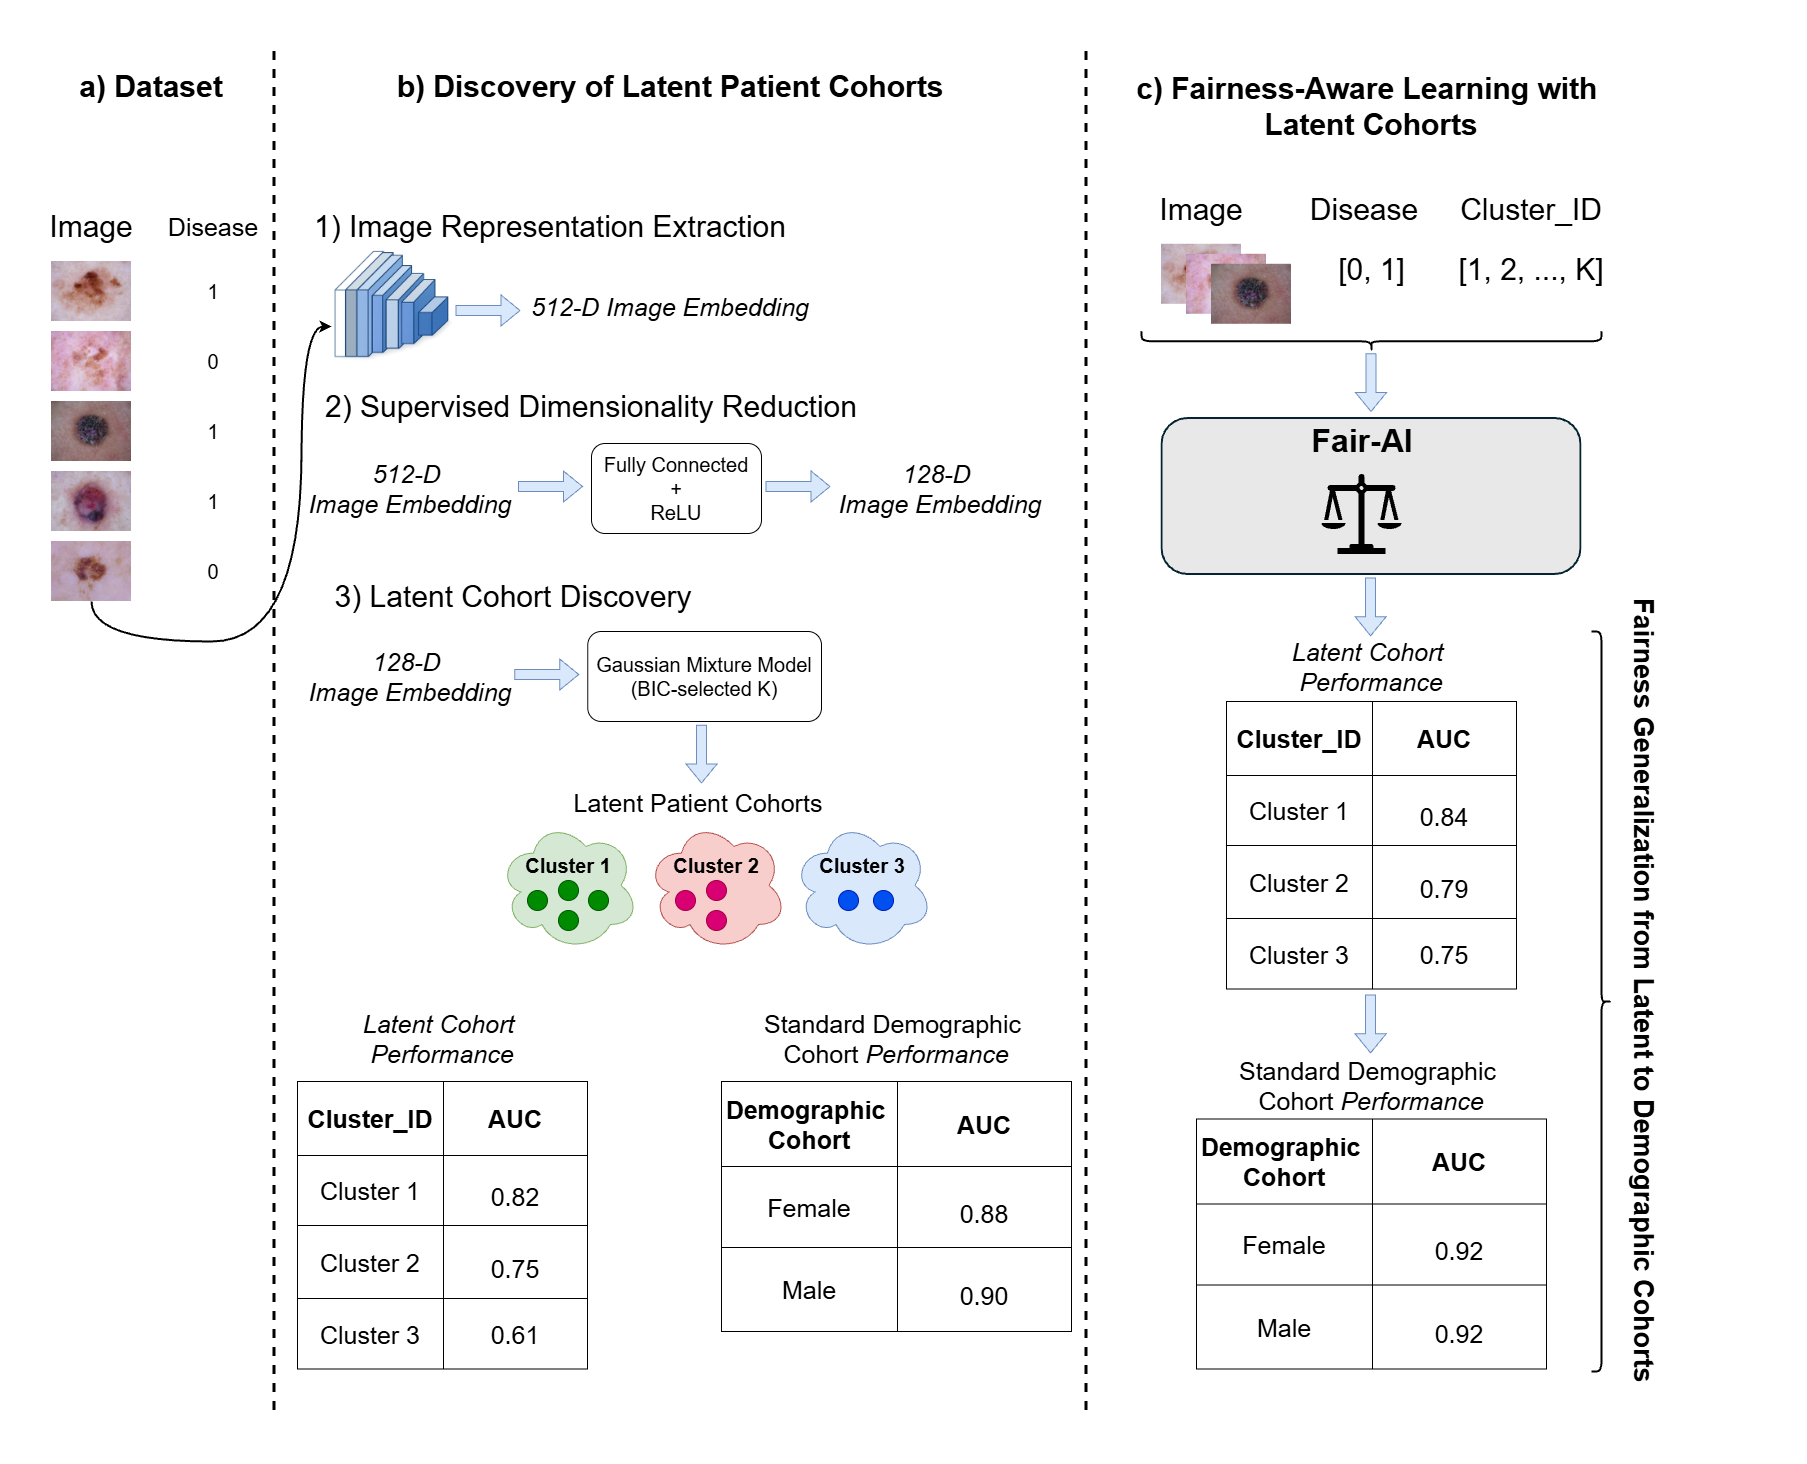
Overview of the proposed Label-Free Hidden-Cohort Fairness (LHCF) framework. LHCF discovers appearance-based hidden cohorts via representation learning and clustering, and subsequently performs fairness-aware training over these latent subpopulations. This approach enables fairness improvements learned from hidden cohorts to generalize to standard visible demographic cohorts, without requiring demographic labels during training. From a real-world perspective, this avoids reliance on predefined sensitive attributes, which may be missing, noisy, incomplete, or unavailable due to privacy constraints, enabling more scalable and robust fairness optimization.
Strengths
- Fairness Beyond Predefined Demographic Attributes. Conventional fairness approaches typically optimize performance across predefined demographic groups, such as sex, age, or ethnicity. However, these visible attributes may only weakly align with the latent factors that drive model behaviour and performance disparities. LHCF moves beyond this restriction by discovering appearance-based hidden cohorts directly from learned image representations and using these cohorts for fairness optimization. This allows the framework to address potential sources of disparity that may not be captured by conventional demographic partitions.
- Identification and Mitigation of Hidden Stratification. Meaningful vulnerable subpopulations can remain hidden within medical imaging datasets even when standard demographic groups are considered. Such appearance-based cohorts may expose model blind spots and performance disparities that are not apparent from demographic evaluation alone. LHCF explicitly discovers these latent patient cohorts from image embeddings and subsequently treats the discovered cohort identities as sensitive attributes during fairness-aware learning, enabling fairness optimization to target hidden sources of model disparity rather than relying exclusively on known demographic groups.
- Demographic-Label-Free Fairness Optimization. Fairness methods that depend on demographic annotations can be difficult to deploy in real-world medical imaging settings because sensitive attributes may be missing, noisy, incomplete, or unavailable because of privacy constraints. LHCF reduces this dependency by constructing the groups required for fairness optimization directly from image representations. Consequently, demographic labels are not required during fairness-aware training, making the framework applicable to datasets where reliable sensitive-attribute annotations are unavailable.
Limitations and Future Directions
- Clinical Validation of Hidden-Cohort Quality. LHCF discovers hidden cohorts in a data-driven manner from learned image representations, and the current framework quantitatively evaluates the characteristics and quality of these discovered cohorts. However, quantitative measures alone cannot fully establish whether the discovered appearance-based cohorts correspond to clinically meaningful latent phenotypes or clinically relevant sources of hidden stratification. A key future direction is therefore to incorporate expert-guided assessment, involving relevant clinicians, radiologists, dermatologists, or other domain experts depending on the imaging modality. Experts could examine representative samples and characteristics from each discovered cohort to determine whether the observed grouping reflects clinically meaningful visual patterns, disease characteristics, or other relevant latent factors. Combining quantitative cohort-quality measures with expert assessment could provide stronger evidence for the clinical interpretability and relevance of the hidden cohorts discovered by LHCF.
-
Reproducibility of Hidden-Cohort Discovery and Downstream Fairness Optimization.
Hidden-cohort discovery is an upstream stage of the LHCF pipeline: image representations are first clustered using an unsupervised GMM-based procedure, and the resulting
Cluster_IDassignments are subsequently used as sensitive attributes by the downstream FairAI model. Because this upstream clustering process is unsupervised and can be sensitive to factors such as initialization and the learned representation, different clustering runs may produce variations in cohort composition and sample assignments. This variability is particularly important for LHCF because changes in the discovered cohorts can propagate to the downstream fairness optimization stage: the FairAI method may effectively optimize fairness over different cohort definitions across runs, potentially affecting the reproducibility of the final accuracy and fairness results. Future work will therefore focus on stabilizing the hidden-cohort discovery stage, evaluating cluster stability across repeated runs, and reducing the propagation of upstream clustering variability into downstream fairness-aware learning. This would improve the end-to-end reproducibility and reliability of LHCF.
Training Protocol and Data Splits
Our Label-Free Hidden-Cohort Fairness (LHCF) framework consists of two stages: (i) hidden cohort discovery and (ii) fairness-aware training. The entire pipeline is designed to be fully split-aware, ensuring no information leakage between training, validation, and test sets.
Hidden Cohort Discovery (Step 1)
The first stage performs unsupervised discovery of latent cohorts from image representations. This process consists of three components: (i) image representation learning, (ii) supervised dimensionality reduction, and (iii) clustering via Gaussian Mixture Models (GMM) with model selection using the Bayesian Information Criterion (BIC).
For representation learning and supervised dimensionality reduction, models are trained using only the training split, with validation data used exclusively for model selection. Specifically, models are trained for up to 60 epochs using the Adam optimizer with a learning rate of 1e-4 and weight decay of 1e-4. Early stopping is applied based on stagnation of the overall validation AUC for 10 consecutive epochs, and the best checkpoint is selected using validation performance.
To ensure a fully split-aware pipeline and avoid any information leakage, the GMM is fitted using representations extracted from the combined training and validation sets only, after model selection has been completed. The number of clusters is determined via BIC evaluated on these representations. The test set is strictly held out during both model training and GMM fitting.
At inference time, cluster assignments for test samples are obtained by applying the fitted GMM (trained on train+validation representations) to the test representations. This ensures that hidden cohort discovery is performed without access to test data, while allowing consistent cohort assignment across all splits.
Fairness-Aware Training (Step 2)
In the second stage, we perform fairness-aware training using the discovered hidden cohort identities as sensitive attributes. While multiple FairAI methods are evaluated in our study, we detail here the training protocol of Fair Distillation for Hidden-Cohort Fairness (FairDi+LHCF), as it achieves the best overall performance and is used extensively in our ablation studies.
FairDi+LHCF consists of three sub-steps: backbone pre-training (Step 0), cohort-specific teacher training (Step 1), and student distillation (Step 2).
In Step 0 (backbone pre-training), the model is trained using only the training split, with validation data used exclusively for model selection. Models are trained for up to 60 epochs using the Adam optimizer with a learning rate of 1e-4 and weight decay of 1e-4. Early stopping is applied based on stagnation of the overall validation AUC for 10 consecutive epochs, and the best checkpoint is selected using validation performance.
In Step 1 (hidden cohort-specific teacher training), separate teacher models are trained for each discovered cohort. Each teacher is initialized from the pretrained backbone, with the backbone (ResNet18) frozen and only the final classifier trained. Training uses SGD with momentum 0.9, a learning rate of 1e-5, and weight decay of 1e-5, and is performed using only the training split, with early stopping based on cohort-specific validation AUC.
In Step 2 (student training), a single student model is trained via knowledge distillation from all cohort-specific teachers. The student is initialized from the pretrained backbone, with the backbone (ResNet18) frozen and only the final classifier trained, and optimized using SGD with the same hyperparameters as the teacher models. Early stopping is based on overall validation AUC. The student learns to aggregate knowledge from all specialized teachers to balance performance across cohorts.
Across all stages, the training protocol is strictly split-aware: the training split is used for model optimization, the validation split for model selection and early stopping, and the test split is held out entirely for final evaluation. Hidden cohort assignments derived in Step 1 are applied consistently across all splits without refitting or adaptation on test data, ensuring a leakage-free evaluation.
All models are implemented in PyTorch 2.2 and trained on an NVIDIA RTX A6000 GPU.
Poster
Click on the poster to view the full-resolution PDF.
BibTeX
@InProceedings{MasMil_Fairness_MICCAI2026,
        author = {Masroor, Milad AND Nguyen, Cuong AND Wells, Kevin AND Carneiro, Gustavo},
        title = {{Fairness Beyond Demographics: Optimizing Performance Across Appearance-Based Hidden Cohorts in Medical Imaging}},
        booktitle = {Medical Image Computing and Computer Assisted Intervention -- MICCAI 2026},
        year = {2026},
        publisher = {Springer Nature Switzerland},
        volume = {LNCS 16882},
        month = {September},
        page = {pending}
}